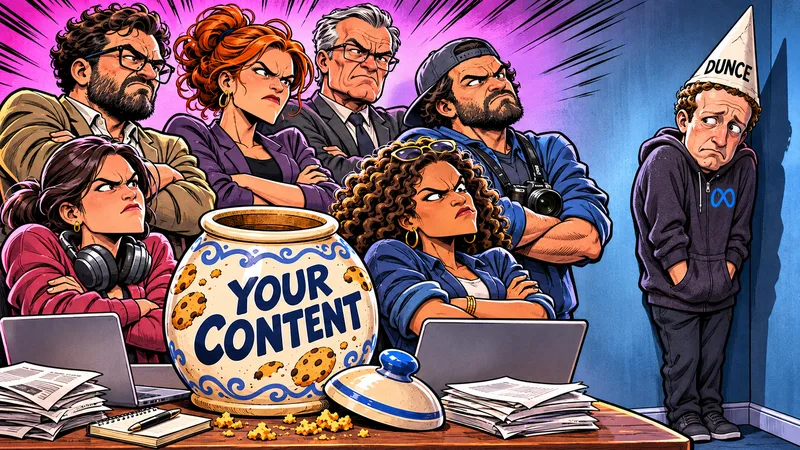
Meta has backed down from controversial new rules that could have given it sweeping permission to collect content from websites linked to Facebook and Instagram business accounts.
Apparently, having access to billions of users wasn’t enough. Meta wanted a bigger helping of everyone else’s content, too.
What Was Meta Trying to Do?
In October, Meta proposed new business terms allowing its automated crawlers to collect information from websites connected to business accounts. The original wording even mentioned using that content to train Meta products, raising fears that publishers’ work could be scooped up for AI development without separate permission or payment.
After criticism, Meta removed the word “train.” But legal experts warned the revised rules still gave the company broad access to website content. It was another major META fail.
Publishers Weren’t Having It
Media companies pushed back. Courts in Norway and Brazil blocked the proposed terms, while UK regulators launched an investigation.
The concern was simple: Why should running a Facebook business account potentially give Meta permission to use content from your independent website?
That’s like renting a booth at a shopping mall and discovering the landlord thinks it owns everything in your warehouse.
Meta Backs Down. For Now.
On November 5, Meta indefinitely paused the changes.
The company insists the proposed terms weren’t intended to expand its existing website-crawling practices.
But there’s a catch: The rules are paused, not permanently cancelled. Meta could introduce another version later.
For website owners, the message is straightforward: keep an eye on Meta’s policies, understand your website’s crawler settings, and don’t rely entirely on Facebook or Instagram to reach your audience.
The bottom line? If Meta wants to use somebody else’s content, here’s a revolutionary concept: ask permission and pay for it. We know Zuckerberg can afford it.
Don’t Want Meta Crawling Your Website? Fight Back.
Here’s something Meta probably won’t advertise: website owners have ways to keep its AI crawlers out. (At least for now.)
You can add instructions to your website’s robots.txt file telling Meta’s AI bots to stay away. For stronger protection, services like Cloudflare can actively block unwanted crawlers or limit how often they access your site.
Neither solution is foolproof, but you don’t have to put put the welcome mat.
Want to stop Meta’s bots from crawling your website? Read our free guide to blocking Meta AI crawlers and protecting your content.
Sources:
- Ars Technica — Meta Abandons Controversial Commercial Terms Update
- Nieman Journalism Lab — Meta Pulls Down Controversial Terms
More AI news, tools, deals and opportunities at MonkeyButtAI.com.